AI Coding Agents in Production Mobile Teams: What Changed in 2026
How agentic coding tools actually changed mobile delivery velocity, code review practices, and estimation accuracy for a working Flutter and Android team through 2026.
Read ArticleEngineering notes from real delivery trenches
Deep dives on autonomous AI agents, MCP architectures, distributed systems, and high-performance client engineering.
Showing 146 articles
Quick Jump
How agentic coding tools actually changed mobile delivery velocity, code review practices, and estimation accuracy for a working Flutter and Android team through 2026.
Read ArticleA practical, incremental migration path for moving a years-old Android app from tangled Activity-based logic to a testable, maintainable separation of concerns without a risky full rewrite.
Read ArticleEvent ingestion, offline buffering, and dashboard freshness patterns for mobile apps that need live analytics without draining battery or overwhelming the backend.
Read ArticleA practical framework for scoping fixed-price mobile app engagements so scope creep, unclear requirements, and platform surprises don't turn a profitable project into a loss.
Read ArticleA practical comparison and integration guide for the three payment gateways most common in mobile marketplace apps, covering webhooks, payouts, and failure handling.
Read ArticleRunning production AI workloads, media processing, and multi-service background jobs on one owned machine with PM2, Docker, Redis, and Caddy — without a cloud bill that scales with usage.
Read ArticleA practical scoring framework for deciding between Flutter and native iOS/Android development, based on team size, timeline, performance needs, and long-term maintenance cost.
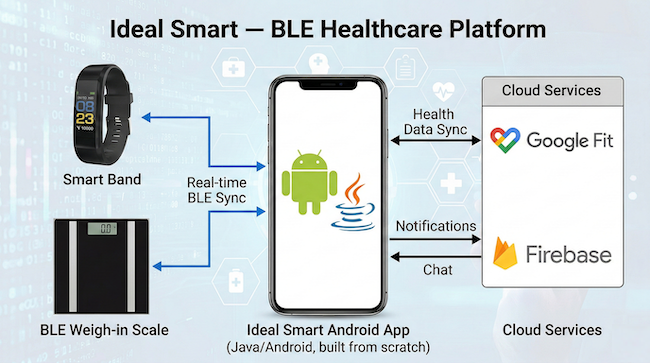
Read ArticleConnection reliability, reconnect strategy, and data integrity patterns for Bluetooth Low Energy device integration in mobile apps that can't afford dropped readings.
Read ArticleTenant isolation, data partitioning, and checkout reliability patterns for marketplace platforms that need to scale from one seller to thousands without a rewrite.
Read ArticleHow to design conflict-safe local-first sync for Flutter apps that stay usable on flaky networks, with real patterns for queueing, conflict resolution, and backpressure.
Read ArticleIn chatbots, token consumption grows linearly. In autonomous agents, it grows quadratically. Here is how AST pruning, tool output trimming, and rolling checkpoints cut costs by 65%.
Read ArticleHow to combine headless browsers with AI agents to build systems that can see, navigate, and act on the web autonomously, with real production guardrails.
Read ArticleHow to stop autonomous AI agents from leaking API keys and credentials when executing shell commands, reading files, and calling tools.
Read ArticleA practical guide to Wrangler CLI: multi-environment configuration, KV and D1 database bindings, secret management, and fast edge deployments.
Read ArticleWhy naive while-loops fail in production AI agents, and how to build resilient execution engines with SQLite WAL journals, retry budgets, and idempotent tool execution.
Read ArticleHow to stream LLM responses into Flutter applications at 60 FPS, protect private API keys behind an edge proxy, and handle spotty mobile connections gracefully.
Read ArticleHow Model Context Protocol works in practice: connecting LLMs to databases, internal APIs, and terminal tools over stdio and SSE without writing bespoke glue code.
Read ArticleHow to design a web stack that handles AI crawlers and automation traffic without hurting real users, while protecting content value and controlling infrastructure cost.
Read ArticleWhat an AI-native engineering stack should look like in real production teams: clear contracts, governed agent actions, and TypeScript-first execution across services.
Read ArticleA production FinOps blueprint for AI features: forecast spend from product behavior, enforce token budgets safely, and route models by business value instead of hype.
Read ArticleA practical governance architecture for AI products that blocks prompt injection, enforces policy at runtime, and keeps enterprise security teams confident during rollout.
Read ArticleHow to run agentic systems in production without giving up reliability, cost control, or operational clarity. A practical model for orchestration, guardrails, and measurable outcomes.
Read ArticleWhat it really takes to deliver "Governance Dashboards for CTOs" without operational surprises. Shows how to harden risky workflows while keeping rollout and rollback paths operationally safe.
Read Article"Security Reviews for MCP Tool Integrations", translated into an executable engineering playbook. Focuses on governance mechanisms that pass security review without slowing engineering output.
Read ArticleA field guide to "AI Output Moderation Pipelines" for teams shipping live products. Shows how to harden risky workflows while keeping rollout and rollback paths operationally safe.
Read ArticleThis post turns "Data Residency Routing at Runtime" into concrete architecture and delivery decisions. Breaks down practical guardrails for permissions, compliance boundaries, and forensic traceability. Every recommendation ties to latency, cost, or reliability.
Read Article"Compliance Environments as Code": a practical blueprint for teams that need speed and reliability together. Focuses on governance mechanisms that pass security review without slowing engineering output.
Read Article"Model Explainability Logs for Regulated Industries" is mostly a systems problem, and this post breaks down the working system. Breaks down practical guardrails for permissions, compliance boundaries, and forensic traceability. Built for real systems, not demos.
Read ArticleIf "Blast Radius Mapping Before Every Deploy" is on your roadmap, this is the implementation path that scales. Includes CI/CD and rollout controls that increase release cadence without raising failure rate. No rewrite assumptions, only pragmatic execution steps.
Read ArticleBehind "Kill Switch Architecture for Critical Features": what has to be true in production for this to work. Breaks down delivery mechanics for faster shipping with lower incident risk. Built for real systems, not demos.
Read ArticleA field guide to "Rollback-First Deployment Design" for teams shipping live products. Focuses on contract discipline, rollback readiness, and safer production release behavior.
Read ArticleThis post turns "Production Replay Testing With Real Logs" into concrete architecture and delivery decisions. Includes implementation-level decisions with measurable trade-offs and clear control points. No rewrite assumptions, only pragmatic execution steps.
Read Article"Shadow Traffic for Risky Refactors": a practical blueprint for teams that need speed and reliability together. Shows release-engineering patterns for teams operating under uptime and deadline pressure.
Read ArticleUse this as a production map for "Contract Testing in Polyglot Stacks", including failure boundaries and controls. Breaks down delivery mechanics for faster shipping with lower incident risk. Every recommendation ties to latency, cost, or reliability.
Read ArticleFrom planning to rollout, "Backward-Compatible API Evolution" needs more than one clever trick. Focuses on contract discipline, rollback readiness, and safer production release behavior.
Read Article"Schema Migration Strategies Without Downtime" is mostly a systems problem, and this post breaks down the working system. Includes CI/CD and rollout controls that increase release cadence without raising failure rate. Focused on outcomes, not tool hype.
Read ArticleWhat it really takes to deliver "Coordinated Releases Across Web, Mobile, and API" without operational surprises. Shows mobile delivery decisions that hold up under growth, traffic spikes, and team scaling.
Read ArticleIf "Release Trains for Multi-App Ecosystems" is on your roadmap, this is the implementation path that scales. Breaks down AI architecture choices across inference, orchestration, and rollout safety. Built for real systems, not demos.
Read ArticleA field guide to "FinOps Workflows for Engineering Teams" for teams shipping live products. Shows how to make unit economics visible before cost drift becomes a release blocker.
Read ArticleThis post turns "Cost Dashboards for Product Managers" into concrete architecture and delivery decisions. Breaks down FinOps decisions with measurable trade-offs across spend, performance, and growth. Built for real systems, not demos.
Read ArticleFrom planning to rollout, "Budget Alerts That Actually Prevent Outages" needs more than one clever trick. Shows how to make unit economics visible before cost drift becomes a release blocker.
Read Article"Autoscaling LLM Workers Without Cold Starts" is mostly a systems problem, and this post breaks down the working system. Breaks down AI architecture choices across inference, orchestration, and rollout safety. Every recommendation ties to latency, cost, or reliability.
Read ArticleWhat it really takes to deliver "Spot Instances for AI Workers: Risk Patterns" without operational surprises. Focuses on deploying AI features with measurable ROI and controlled operational risk.
Read ArticleBehind "Platform vs DevOps: When to Split the Function": what has to be true in production for this to work. Breaks down platform engineering decisions that improve speed without creating tool sprawl. Built for real systems, not demos.
Read ArticleThis post turns "Reducing Cognitive Load With Platform Tooling" into concrete architecture and delivery decisions. Includes repeatable platform patterns that reduce cognitive load and unblock product teams. Focused on outcomes, not tool hype.
Read ArticleUse this as a production map for "Dependency Graphs for Microservice Risk", including failure boundaries and controls. Breaks down common production failure modes and the safeguards that prevent repeat issues. Built for real systems, not demos.
Read ArticleFrom planning to rollout, "Scorecards for Service Readiness" needs more than one clever trick. Focuses on self-service workflows, golden paths, and durable operational control points.
Read Article"Platform SLAs for Product Teams" is mostly a systems problem, and this post breaks down the working system. Includes repeatable platform patterns that reduce cognitive load and unblock product teams. No rewrite assumptions, only pragmatic execution steps.
Read ArticleWhat it really takes to deliver "Environment Templates for SaaS Modules" without operational surprises. Shows where standardization helps and where flexibility must stay for delivery to remain fast.
Read ArticleA field guide to "Caching Tool Responses to Reduce LLM Calls" for teams shipping live products. Shows guardrails that prevent agent chaos while preserving product and engineering velocity.
Read ArticleUse this as a production map for "Deterministic vs Generative Agent Workflows", including failure boundaries and controls. Breaks down controls for idempotency, sandboxing, and human-in-the-loop approvals. Built for real systems, not demos.
Read ArticleFrom planning to rollout, "Multi-Agent Orchestration Without Chaos" needs more than one clever trick. Focuses on making agent workflows auditable, retry-safe, and predictable under real load.
Read ArticleIf "Human-in-the-Loop Gates for High-Risk Actions" is on your roadmap, this is the implementation path that scales. Breaks down controls for idempotency, sandboxing, and human-in-the-loop approvals. Every recommendation ties to latency, cost, or reliability.
Read Article"Agent Timeouts, Retries, and Idempotency", translated into an executable engineering playbook. Focuses on making agent workflows auditable, retry-safe, and predictable under real load.
Read ArticleBehind "Sandboxing Agent Tool Calls Safely": what has to be true in production for this to work. Includes policy controls, auditability, and tenant isolation patterns built for real production risk. Focused on outcomes, not tool hype.
Read ArticleThis post turns "Designing MCP Servers for Internal Tooling" into concrete architecture and delivery decisions. Breaks down controls for idempotency, sandboxing, and human-in-the-loop approvals. Built for real systems, not demos.
Read Article"Cost Guardrails for Autonomous Agents" is mostly a systems problem, and this post breaks down the working system. Includes metering strategy, budget caps, and pricing telemetry to protect margins in production. No rewrite assumptions, only pragmatic execution steps.
Read ArticleWhat it really takes to deliver "Logging and Auditing Agent Decisions" without operational surprises. Shows how to harden risky workflows while keeping rollout and rollback paths operationally safe.
Read ArticleA field guide to "Tool Permission Models for AI Agents in Production" for teams shipping live products. Shows how to harden risky workflows while keeping rollout and rollback paths operationally safe.
Read ArticleIf "Self-Service Environments Without DevOps Bottlenecks" is on your roadmap, this is the implementation path that scales. Breaks down platform engineering decisions that improve speed without creating tool sprawl. Every recommendation ties to latency, cost, or reliability.
Read Article"Platform Cost Attribution per Team": a practical blueprint for teams that need speed and reliability together. Shows how to make unit economics visible before cost drift becomes a release blocker.
Read Article"Golden Paths: Standardizing Service Creation", translated into an executable engineering playbook. Focuses on self-service workflows, golden paths, and durable operational control points.
Read ArticleBehind "Internal Developer Platforms for Small Teams": what has to be true in production for this to work. Includes repeatable platform patterns that reduce cognitive load and unblock product teams. Focused on outcomes, not tool hype.
Read ArticleBehind "Prompt Injection Defense at the Gateway Layer": what has to be true in production for this to work. Includes policy controls, auditability, and tenant isolation patterns built for real production risk. No rewrite assumptions, only pragmatic execution steps.
Read ArticleFrom planning to rollout, "Tenant-Level Encryption Key Management" needs more than one clever trick. Shows how to harden risky workflows while keeping rollout and rollback paths operationally safe.
Read ArticleUse this as a production map for "RBAC for AI Tooling and Data Access", including failure boundaries and controls. Includes policy controls, auditability, and tenant isolation patterns built for real production risk. Focused on outcomes, not tool hype.
Read ArticleWhat it really takes to deliver "AI Audit Trails for Enterprise Customers" without operational surprises. Focuses on governance mechanisms that pass security review without slowing engineering output.
Read Article"Cost-Aware Rate Limiting for AI Endpoints" is mostly a systems problem, and this post breaks down the working system. Includes metering strategy, budget caps, and pricing telemetry to protect margins in production. Focused on outcomes, not tool hype.
Read ArticleWhat it really takes to deliver "Preventing Free Tier Abuse at the API Layer" without operational surprises. Shows concrete guidance you can map directly to engineering execution.
Read ArticleIf "Tier Entitlement Systems for Multi-Tenant SaaS" is on your roadmap, this is the implementation path that scales. Breaks down common production failure modes and the safeguards that prevent repeat issues. Built for real systems, not demos.
Read Article"Experimenting With Pricing Using Feature Toggles", translated into an executable engineering playbook. Focuses on cost controls that reduce cloud burn without slowing delivery or harming reliability.
Read Article"When to Kill an AI Feature Based on Cost Curves", translated into an executable engineering playbook. Focuses on cost controls that reduce cloud burn without slowing delivery or harming reliability.
Read ArticleUse this as a production map for "Forecasting AI Spend From Product Metrics", including failure boundaries and controls. Includes metering strategy, budget caps, and pricing telemetry to protect margins in production. No rewrite assumptions, only pragmatic execution steps.
Read Article"Token Budgets per Feature Flag": a practical blueprint for teams that need speed and reliability together. Focuses on cost controls that reduce cloud burn without slowing delivery or harming reliability.
Read ArticleIf "GPU vs CPU Inference Cost Models" is on your roadmap, this is the implementation path that scales. Includes metering strategy, budget caps, and pricing telemetry to protect margins in production. Focused on outcomes, not tool hype.
Read Article"Unit Economics of an AI Request", translated into an executable engineering playbook. Shows how to make unit economics visible before cost drift becomes a release blocker.
Read ArticleFrom planning to rollout, "AI Feature Flags in Mobile: Ship Safely Without Breaking Production" needs more than one clever trick. Shows mobile delivery decisions that hold up under growth, traffic spikes, and team scaling.
Read ArticleWhat it really takes to deliver "Token Cost Optimization Strategies for Mobile AI Features" without operational surprises. Focuses on cost controls that reduce cloud burn without slowing delivery or harming reliability.
Read ArticleIf "AI-Generated Test Cases for Flutter/Kotlin: Cut QA Time by 40%" is on your roadmap, this is the implementation path that scales. Includes mobile architecture patterns for backend alignment, release speed, and production reliability. Focused on outcomes, not tool hype.
Read Article"Queue-Based AI Processing for Mobile (Async Workers + PM2)", translated into an executable engineering playbook. Shows mobile delivery decisions that hold up under growth, traffic spikes, and team scaling.
Read ArticleBehind "AI for Legacy Mobile Apps: Add Smart Features Without Refactoring": what has to be true in production for this to work. Breaks down app release cadence, API boundaries, and practical failure-recovery controls. Built for real systems, not demos.
Read ArticleA field guide to "From Static Feeds to AI Personalization in Mobile Apps" for teams shipping live products. Focuses on shipping mobile features faster without sacrificing operational stability.
Read ArticleThis post turns "Self-Hosted vs OpenAI for Production Mobile Apps: Real Cost Numbers" into concrete architecture and delivery decisions. Includes metering strategy, budget caps, and pricing telemetry to protect margins in production. No rewrite assumptions, only pragmatic...
Read Article"AI-Powered Search for Mobile Apps Using Embeddings + Edge Caching": a practical blueprint for teams that need speed and reliability together. Shows mobile delivery decisions that hold up under growth, traffic spikes, and team scaling.
Read ArticleUse this as a production map for "5 AI Features That Reduce Support Costs in Mobile Apps", including failure boundaries and controls. Breaks down FinOps decisions with measurable trade-offs across spend, performance, and growth. Every recommendation ties to latency, cost, or...
Read ArticleFrom planning to rollout, "Add AI to Your Existing Mobile App in 14 Days: A Fixed-Scope Playbook" needs more than one clever trick. Focuses on shipping mobile features faster without sacrificing operational stability.
Read Article"Multi-Tenant AI Features for SaaS Mobile Apps" is mostly a systems problem, and this post breaks down the working system. Includes mobile architecture patterns for backend alignment, release speed, and production reliability. Focused on outcomes, not tool hype.
Read ArticleIf "Token Cost Optimization for AI Features at Scale" is on your roadmap, this is the implementation path that scales. Breaks down FinOps decisions with measurable trade-offs across spend, performance, and growth. Every recommendation ties to latency, cost, or reliability.
Read Article"Offline AI Strategies for Mobile (What Actually Works)", translated into an executable engineering playbook. Focuses on shipping mobile features faster without sacrificing operational stability.
Read ArticleBehind "Event-Driven AI Pipelines for Mobile Products": what has to be true in production for this to work. Includes mobile architecture patterns for backend alignment, release speed, and production reliability. Focused on outcomes, not tool hype.
Read ArticleA field guide to "Designing an AI-Ready Mobile Architecture in 2026" for teams shipping live products. Shows mobile delivery decisions that hold up under growth, traffic spikes, and team scaling.
Read ArticleThis post turns "Observability for AI Features in Mobile Apps" into concrete architecture and delivery decisions. Breaks down app release cadence, API boundaries, and practical failure-recovery controls. Built for real systems, not demos.
Read Article"Queue-Based AI Processing for Mobile (Orchestrator -> Worker Model)": a practical blueprint for teams that need speed and reliability together. Focuses on shipping mobile features faster without sacrificing operational stability.
Read ArticleUse this as a production map for "Edge AI for Mobile: Reducing Latency with Cloudflare Workers", including failure boundaries and controls. Includes mobile architecture patterns for backend alignment, release speed, and production reliability. No rewrite assumptions, only...
Read ArticleFrom planning to rollout, "Running an AI Inference Worker with PM2 for Mobile Apps" needs more than one clever trick. Shows mobile delivery decisions that hold up under growth, traffic spikes, and team scaling.
Read Article"Self-Hosted vs OpenAI for Mobile Backends: Cost Breakdown" is mostly a systems problem, and this post breaks down the working system. Breaks down FinOps decisions with measurable trade-offs across spend, performance, and growth. Every recommendation ties to latency, cost, or...
Read ArticleWhat it really takes to deliver "AI for Refactoring Legacy Mobile Codebases Safely" without operational surprises. Focuses on shipping mobile features faster without sacrificing operational stability.
Read Article"Prompt-to-Feature: Turning Product Specs Into Production Code", translated into an executable engineering playbook. Shows implementation-level guidance for AI features that must survive real user load.
Read ArticleBehind "AI-Generated Test Cases for Flutter/Kotlin Apps": what has to be true in production for this to work. Breaks down app release cadence, API boundaries, and practical failure-recovery controls. Every recommendation ties to latency, cost, or reliability.
Read ArticleA field guide to "Using LLMs for API Contract Generation Before Coding" for teams shipping live products. Focuses on deploying AI features with measurable ROI and controlled operational risk.
Read ArticleThis post turns "My AI-Assisted Mobile Development Workflow That Cuts Build Time 50%" into concrete architecture and delivery decisions. Includes mobile architecture patterns for backend alignment, release speed, and production reliability. Focused on outcomes, not tool hype.
Read Article"AI Personalization Pipelines for Mobile Using APIs + Edge Caching": a practical blueprint for teams that need speed and reliability together. Shows mobile delivery decisions that hold up under growth, traffic spikes, and team scaling.
Read ArticleUse this as a production map for "AI for SaaS Mobile Apps: Where It Creates Real ROI", including failure boundaries and controls. Breaks down app release cadence, API boundaries, and practical failure-recovery controls. Built for real systems, not demos.
Read ArticleFrom planning to rollout, "From Chatbot to Revenue: AI Features Users Actually Pay For" needs more than one clever trick. Focuses on deploying AI features with measurable ROI and controlled operational risk.
Read Article"7 AI Features That Increase Retention in Mobile Apps" is mostly a systems problem, and this post breaks down the working system. Includes durable data contracts, quality checks, and lifecycle controls that survive product change. No rewrite assumptions, only pragmatic...
Read ArticleWhat it really takes to deliver "How to Add AI to a Live Mobile App Without Rewriting the Backend" without operational surprises. Shows mobile delivery decisions that hold up under growth, traffic spikes, and team scaling.
Read ArticleIf "Crash-Resilient Mobile Systems: Beyond Firebase Crashlytics" is on your roadmap, this is the implementation path that scales. Breaks down app release cadence, API boundaries, and practical failure-recovery controls. Every recommendation ties to latency, cost, or reliability.
Read ArticleBehind "Designing Mobile Apps for Multi-Tenant SaaS": what has to be true in production for this to work. Includes mobile architecture patterns for backend alignment, release speed, and production reliability. No rewrite assumptions, only pragmatic execution steps.
Read ArticleA field guide to "Feature Flag Systems for Mobile at Scale" for teams shipping live products. Shows mobile delivery decisions that hold up under growth, traffic spikes, and team scaling.
Read ArticleThis post turns "API-First Mobile Development: Contracts Before Code" into concrete architecture and delivery decisions. Breaks down app release cadence, API boundaries, and practical failure-recovery controls. Every recommendation ties to latency, cost, or reliability.
Read Article"Modular Mobile Architecture for Multi-Team Development": a practical blueprint for teams that need speed and reliability together. Focuses on shipping mobile features faster without sacrificing operational stability.
Read ArticleUse this as a production map for "Offline AI on Mobile: What’s Possible in 2026", including failure boundaries and controls. Includes mobile architecture patterns for backend alignment, release speed, and production reliability. Focused on outcomes, not tool hype.
Read ArticleFrom planning to rollout, "Why Most AI Features Fail in Production Mobile Apps" needs more than one clever trick. Shows mobile delivery decisions that hold up under growth, traffic spikes, and team scaling.
Read Article"AI Features That Users Actually Pay For in Mobile Apps" is mostly a systems problem, and this post breaks down the working system. Breaks down app release cadence, API boundaries, and practical failure-recovery controls. Built for real systems, not demos.
Read ArticleWhat it really takes to deliver "Self-Hosted LLM for Mobile: Cost, Latency, and Trade-offs" without operational surprises. Focuses on cost controls that reduce cloud burn without slowing delivery or harming reliability.
Read ArticleIf "Adding AI to an Existing Mobile App in 7 Days" is on your roadmap, this is the implementation path that scales. Includes mobile architecture patterns for backend alignment, release speed, and production reliability. No rewrite assumptions, only pragmatic execution steps.
Read Article"How to Monitor Mobile Systems End-to-End (App -> API -> DB)", translated into an executable engineering playbook. Shows mobile delivery decisions that hold up under growth, traffic spikes, and team scaling.
Read ArticleA field guide to "Edge Caching Strategies for Mobile APIs" for teams shipping live products. Focuses on shipping mobile features faster without sacrificing operational stability.
Read ArticleThis post turns "Designing a Mobile Stack That Survives Vendor Lock-In" into concrete architecture and delivery decisions. Includes mobile architecture patterns for backend alignment, release speed, and production reliability. No rewrite assumptions, only pragmatic execution...
Read Article"When to Use AWS vs Self-Hosted for Mobile APIs": a practical blueprint for teams that need speed and reliability together. Shows mobile delivery decisions that hold up under growth, traffic spikes, and team scaling.
Read ArticleUse this as a production map for "Running Mobile Backends on a $10 Server: PM2 + Caddy + Cloudflare", including failure boundaries and controls. Breaks down app release cadence, API boundaries, and practical failure-recovery controls. Every recommendation ties to latency,...
Read ArticleFrom planning to rollout, "What Founders Get Wrong When Hiring Mobile Teams" needs more than one clever trick. Focuses on shipping mobile features faster without sacrificing operational stability.
Read Article"The Hidden Cost of Firebase-Only Architectures at Scale" is mostly a systems problem, and this post breaks down the working system. Includes metering strategy, budget caps, and pricing telemetry to protect margins in production. Focused on outcomes, not tool hype.
Read ArticleWhat it really takes to deliver "How to Ship Mobile Features Weekly Without App Store Delays" without operational surprises. Shows mobile delivery decisions that hold up under growth, traffic spikes, and team scaling.
Read ArticleIf "Mobile Is Not the Problem — Your Backend and CI/CD Are" is on your roadmap, this is the implementation path that scales. Breaks down app release cadence, API boundaries, and practical failure-recovery controls. Built for real systems, not demos.
Read Article"Why Most Mobile Projects Fail After Development Is Done", translated into an executable engineering playbook. Focuses on shipping mobile features faster without sacrificing operational stability.
Read ArticleBehind "Building an AI-Ready Mobile Stack Today (Without Overengineering)": what has to be true in production for this to work. Includes mobile architecture patterns for backend alignment, release speed, and production reliability. No rewrite assumptions, only pragmatic...
Read ArticleThis post turns "Cost Comparison: SaaS AI APIs vs Self-Hosted LLM for Production Apps" into concrete architecture and delivery decisions. Breaks down FinOps decisions with measurable trade-offs across spend, performance, and growth. Built for real systems, not demos.
Read Article"Adding AI Features to Existing Mobile Apps Without Rewriting Backend": a practical blueprint for teams that need speed and reliability together. Focuses on shipping mobile features faster without sacrificing operational stability.
Read ArticleUse this as a production map for "Edge -> Orchestrator -> Worker: A Practical AI Architecture for Apps", including failure boundaries and controls. Includes production tactics for latency control, quality drift, and AI cost containment. No rewrite assumptions, only pragmatic...
Read ArticleFrom planning to rollout, "Self-Hosted AI for Mobile Apps: When Not to Use OpenAI" needs more than one clever trick. Shows mobile delivery decisions that hold up under growth, traffic spikes, and team scaling.
Read Article"Observability for Mobile Systems: Logs, Traces, and Crash Intelligence" is mostly a systems problem, and this post breaks down the working system. Breaks down app release cadence, API boundaries, and practical failure-recovery controls. Every recommendation ties to latency,...
Read ArticleWhat it really takes to deliver "Cloudflare for Mobile APIs: Performance, Security, and Cost Wins" without operational surprises. Focuses on governance mechanisms that pass security review without slowing engineering output.
Read ArticleIf "Zero-Downtime Mobile Backend Deployments with PM2 + Caddy" is on your roadmap, this is the implementation path that scales. Includes mobile architecture patterns for backend alignment, release speed, and production reliability. Focused on outcomes, not tool hype.
Read Article"Mobile CI/CD That Actually Works: GitHub Actions + Fastlane + Firebase", translated into an executable engineering playbook. Shows mobile delivery decisions that hold up under growth, traffic spikes, and team scaling.
Read ArticleBehind "How We Cut AWS Bills by 35% for Mobile Backends": what has to be true in production for this to work. Breaks down app release cadence, API boundaries, and practical failure-recovery controls. Built for real systems, not demos.
Read ArticleA field guide to "Feature Flags in Mobile: Ship Faster Without App Store Delays" for teams shipping live products. Focuses on shipping mobile features faster without sacrificing operational stability.
Read Article"API Contract Strategy Between Flutter and Backend Teams": a practical blueprint for teams that need speed and reliability together. Shows mobile delivery decisions that hold up under growth, traffic spikes, and team scaling.
Read ArticleUse this as a production map for "Offline-First Mobile Architecture for Emerging Markets", including failure boundaries and controls. Breaks down app release cadence, API boundaries, and practical failure-recovery controls. Built for real systems, not demos.
Read ArticleFrom planning to rollout, "Designing Mobile Apps That Survive 100K Users Without Rebuilds" needs more than one clever trick. Focuses on shipping mobile features faster without sacrificing operational stability.
Read ArticleA release-day operating checklist with preflight checks, staged rollout gates, and rollback triggers that prevent midnight firefights.
Read ArticleHow to combine Firebase Crashlytics and structured logs into one triage pipeline that cuts alert noise and prioritizes the crash that actually hurts users.
Read ArticleA six-week MVP case study covering vendor onboarding, order orchestration, and payments without creating unpayable technical debt.
Read ArticleA contract-sprint architecture model that protects delivery speed while preventing module sprawl, API drift, and late-stage QA bottlenecks.
Read ArticleField-tested BLE patterns for pairing, reconnects, and packet reliability across Android and iOS under unstable radio conditions.
Read ArticleA sprint-level startup optimization playbook: trace-first diagnostics, startup budgets, and guarded rollout steps that reduce cold-start time without risky rewrites.
Read ArticleNo posts match this query. Try a different keyword or category.